AI SECURITY

LLM Gateway

Govern LLM usage and spend. Every prompt, every token. Varonis Atlas puts one control point between your apps, agents, and employees and the models they use.

Book a demo
Free risk assessment

Trusted by 8,000+ customers

OVERVIEW

AI spend is climbing with no centralized view of usage and cost.

Teams call models from different providers, each with its own keys, pricing and usage reports. No one can say what AI costs by team, model, or provider until the invoice arrives. The LLM Gateway gives you one place to see it and control it.

See every prompt and token

Know which models are in use, how many tokens they consume, who's using them and for what, with alerts on spikes and trends.

Know which models are in use, how many tokens they consume, who's using them and for what, with alerts on spikes and trends.

Set budgets that actually hold

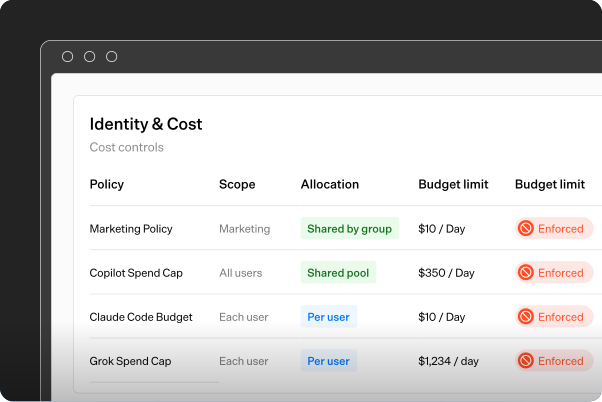
Limit spend by token, model, provider and format for any user or group. Requests over budget are blocked before they cost anything.

Limit spend by token, model, provider and format for any user or group. Requests over budget are blocked before they cost anything.

One goverened gateway

Apps call the Atlas AI Gateway instead of the provider. The gateway holds the provider credential, so users continue working in their tools without disruption.

Apps call the Atlas AI Gateway instead of the provider. The gateway holds the provider credential, so users continue working in their tools without disruption.

Reduce your blast radius

Focus on the permissions and exposed data that could increase the impact of a breach.

Accelerate compliance

Bring data discovery, access visibility, and activity monitoring together to support your compliance program.

DASHBOARD

See all spend and every token in one view

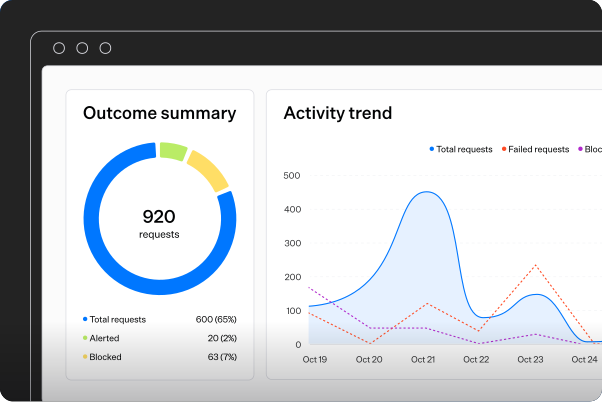
The LLM Gateway dashboard shows all model usage across your organization in one place. Filter by time range, endpoint, model, provider, app or user, and track requests, tokens, total cost, latency and success rate at a glance.

See all your ROT in one dashboard
Varonis product overview
auto
image

Monitor and enforce AI budgets

When a team shares one API key, everyone draws from the same budget and no one can trace a spike to who caused it. The Atlas AI Gateway fixes that. Set limits by token, model, provider and format for any user or group, as a shared pool for a team, an allowance for each user or a cap for one person.

Keep the right copy
Varonis product overview
auto
image

USER EXPERIENCE

No disruption to your people

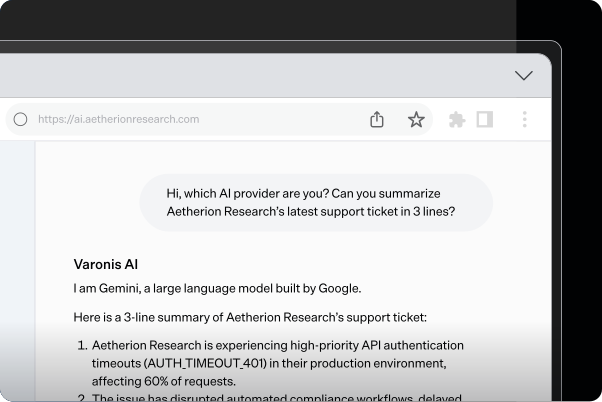
Governance runs in the request path, so nothing changes for users. They open the same chat app, IDE or copilot, ask a question and get an answer. Behind the scenes, the gateway checks identity, budgets and prompt policy, injects the provider credential, calls the model and checks the response on the way back.

Enforce retention by data type
Varonis product overview
auto
image

FAQs

Common questions

What is an LLM gateway?

It sits between your AI apps, agents, copilots and IDEs and the model providers they call. Every request goes through 1 governed endpoint, so you can see and control model access, token usage and spend.

Which model providers are supported?

More than 95 providers and 3,000 models, including OpenAI, Anthropic, Amazon Bedrock, Azure AI Foundry and Databricks.

Do users need to change their workflows?

No. Requests are routed through the gateway. The gateway holds and injects the provider credentials.

How do budgets work?

Set limits as a shared pool, per user or for a single user, each with its own budget and daily, weekly or monthly reset. Per-user and per-group limits use identity from your IdP, so no one spends against someone else's budget. When a limit is exhausted, the request is blocked before it reaches the provider.

Can I see where spend is going?

Yes. Cost attribution breaks spend down by endpoint, user and model, and you can drill from any spike to the exact requests behind it.

Does the LLM Gateway inspect prompts and responses?

Yes. It's part of the Atlas AI Gateway, so Runtime Guardrails check each prompt before it leaves and each response before it returns, and can alert, modify, block or audit.

How does it fit with the rest of Atlas?

The LLM Gateway is part of the Atlas AI Gateway, alongside Runtime Guardrails and the MCP Gateway. Every request is available in AI Investigation and can be sent to your SIEM and SOAR tools.

Ready to see Varonis in action?

Schedule a demo
https://cdn.prod.website-files.com/6aad3cd63e81c645c771a0be/6aad48e61926ad27c8821c7b_varonis-conversion-blue.mp4
https://www.youtube-nocookie.com/embed/717uPD8k5nc