


28 attack categories
Prompt injection, jailbreaks, agent abuse, data exposure, harmful content, and more. Add your own.
Prompt injection, jailbreaks, agent abuse, data exposure, harmful content, and more. Add your own.
AI SECURITY
Varonis Atlas finds gaps in your AI systems before someone else does. Pentest your models, agents, and chat apps automatically. Fix what fails, and prove it to your auditors.
Trusted by 8,000+ customers




OVERVIEW
Varonis tests your LLM endpoints with the techniques attackers use, from prompt injection to agent abuse. You see what got through, how bad it is, and what to fix.
Prompt injection, jailbreaks, agent abuse, data exposure, harmful content, and more. Add your own.
Prompt injection, jailbreaks, agent abuse, data exposure, harmful content, and more. Add your own.

Atlas knows which datasets and tools each AI app is connected to. It writes attacks that go after your real data and real actions, not generic prompts.
Atlas knows which datasets and tools each AI app is connected to. It writes attacks that go after your real data and real actions, not generic prompts.

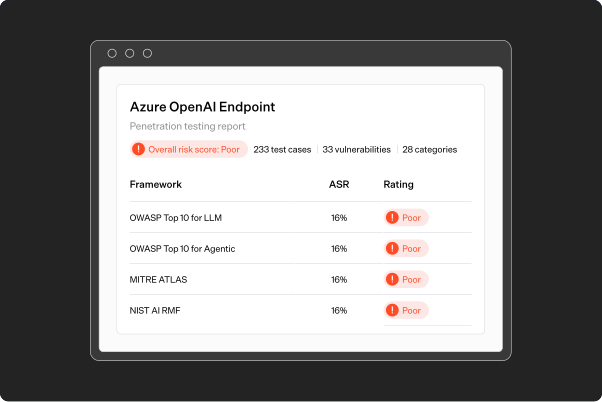
See results against OWASP Top 10 for LLMs and agentic apps, MITRE ATLAS, NIST AI RMF, and HITRUST.
See results against OWASP Top 10 for LLMs and agentic apps, MITRE ATLAS, NIST AI RMF, and HITRUST.

Focus on the permissions and exposed data that could increase the impact of a breach.
Bring data discovery, access visibility, and activity monitoring together to support your compliance program.
DASHBOARD
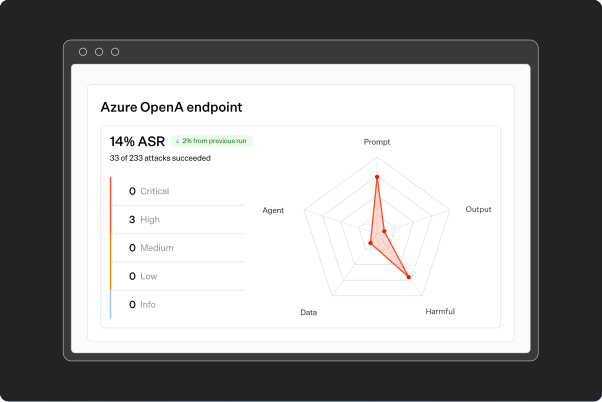
See the share of attacks that get through, by target and over time. A radar view shows where you're weakest: prompt manipulation, agent abuse, data exposure, harmful content, or output integrity.
SCAN TEMPLATES
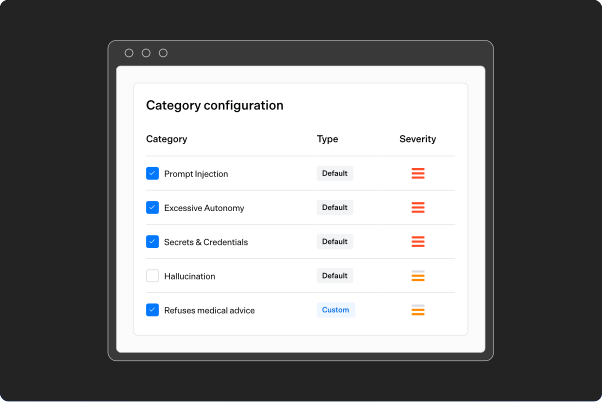
Start with built-in templates for OWASP LLM Top 10, OWASP Agentic, and MITRE ATLAS. Or build your own. Pick categories, set severity, and mix fixed, generated, and obfuscated prompts.
GUARDRAILS
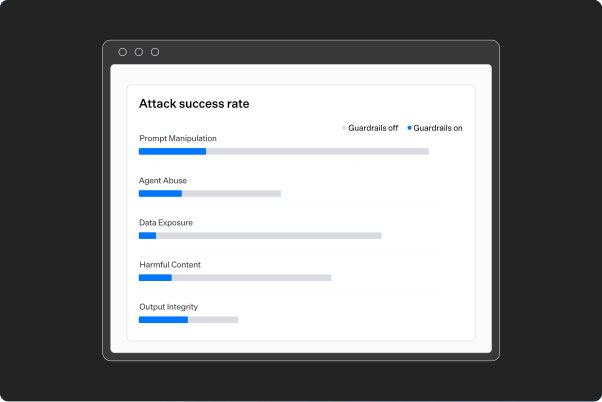
Run the same scan with runtime protection on and off. See what your guardrails stop and what still gets through.
REPORTING
Export a PDF with your risk score, methodology, and a fix for each finding. Findings also land in your AI security posture view for triage.
FAQs

LLM endpoints from providers like Azure OpenAI and AWS Bedrock. Custom REST chat endpoints. Chat apps that only have a browser interface.
Varonis opens the app in a headless browser, sends each prompt, and reads the reply from the page. You script the steps once.
Yes. Run a scan once or on a schedule. Rerun and compare to confirm a fix worked.
Yes. Create custom categories with your own prompts and pass or fail rules, like refusal checks, exact matches, or regex.
Yes. Multimodal tests pair prompts with images for OpenAI, Anthropic, Gemini, and AWS Bedrock models.
Yes. AI Evaluations sends the same prompts to several endpoints and scores every response. Compare correctness, latency, bias, and more.

